CDNA4 dense MFMA builtins#
Matrix Fused Multiply-Add (MFMA) builtins let you issue hardware
matrix multiply-accumulate operations directly from HIP device code on
CDNA4 GPUs (gfx950, MI350 series). Each MFMA instruction multiplies a small
\(\pmb{A}\) fragment by a small \(\pmb{B}\) fragment and accumulates the
result into a \(\pmb{C}\) fragment, all within a single wavefront of 64
lanes. The hardware delivers significantly higher throughput than an equivalent
sequence of scalar fused multiply-add (FMA) instructions.
CDNA4 retains FP32, FP16, BF16, INT8, FP64, FP8, and BF8 shapes from CDNA3
and adds wider-K single-block variants for FP16, BF16, and INT8, plus a new
class of scaled sub-byte builtins (mfma_scale_*) that support FP8, BF8,
FP6 (E2M3 and E3M2), and FP4 (E2M1) input formats with per-block scaling.
The eXtended Float32 (XF32) input format available on CDNA3 is not supported
on CDNA4. See the builtin reference below for the complete list of supported
shapes and formats.
Architecture availability#
The builtins on this page target CDNA4 (gfx950, MI350 series) exclusively.
Equivalent builtins for other CDNA generations are documented on their own
reference pages:
CDNA dense MFMA builtins – CDNA (
gfx908, MI100 series)CDNA2 dense MFMA builtins – CDNA2 (
gfx90a, MI200 series)CDNA3 dense MFMA builtins – CDNA3 (
gfx942, MI300 series)
Naming convention#
All MFMA builtins follow the pattern:
__builtin_amdgcn_mfma_<out_type>_<M>x<N>x<K><in_type>
For FP8 and BF8 builtins, where the \(\pmb{A}\) and \(\pmb{B}\) input types can differ, the pattern is:
__builtin_amdgcn_mfma_<out_type>_<M>x<N>x<K>_<typeA>_<typeB>
out_typeAccumulator element type (
f32,f64, ori32).M,N,KTile dimensions in elements. The instruction computes the contribution of a K-wide panel of \(\pmb{A}\) (\(M \times K\)) and a K-wide panel of \(\pmb{B}\) (\(K \times N\)) to an \(M \times N\) output tile. Each instruction processes one K step; the caller loops over K to accumulate a full matrix product.
in_typeInput element type (
f32,f64,f16,bf16,i8, orxf32).typeA,typeBFor FP8 and BF8 builtins: the element type of the \(\pmb{A}\) and \(\pmb{B}\) matrices respectively. Each is one of
fp8(E4M3 format) orbf8(E5M2 format).
Note
CDNA4 renames several underlying instruction set architecture (ISA)
instructions to include an explicit block count (for example,
v_mfma_f32_32x32x1f32 becomes v_mfma_f32_32x32x1_2b_f32 in
the CDNA4 ISA). The HIP builtin
names (__builtin_amdgcn_mfma_*) are unchanged; the rename is
transparent to HIP device code.
Accumulator layout#
Each MFMA instruction computes one or more independent \(M \times N\) output tiles simultaneously across the 64 lanes of a wavefront. The number of independent tiles is called the block count. It depends on how the \(\pmb{A}\) matrix rows are distributed across lane groups:
Scalar-input variants (FP32 or FP64 \(\pmb{A}\) and \(\pmb{B}\)): each K position occupies a separate group of \(M\) lanes, so \(\text{blocks} = \text{wavefront\_size} / (M \times K)\).
Packed-input variants (FP16, BF16, XF32, INT8, FP8, BF8 \(\pmb{A}\) and \(\pmb{B}\)): all K positions are packed into the register bits of the same lane group, so \(\text{blocks} = \text{wavefront\_size} / M\) regardless of \(K\).
Each block is independent: the \(\pmb{A}\), \(\pmb{B}\), and \(\pmb{C}\)/\(\pmb{D}\) operands of different blocks occupy distinct lane and accVGPR positions and compute separate outer products.
The total number of accVGPRs per lane scales with the block count:
Note
On CDNA4, all four operands (\(\pmb{A}\), \(\pmb{B}\), \(\pmb{C}\), and \(\pmb{D}\)) can reside in either accumulation VGPRs (accVGPRs) or standard architecture VGPRs (archVGPRs). In HIP device code the compiler selects the appropriate register class automatically.
Each of the 64 wavefront lanes maintains its own private accVGPR file. An accVGPR index always refers to a register within one specific lane’s file; the same index in two different lanes denotes two distinct physical registers. The layout tables and formulas in the following sections use accVGPR index as a logical position label; the actual register class (accVGPR or ArchVGPR) is chosen by the compiler and does not affect the layout.
The formulas in the subsections below use the following notation:
\(i\) – zero-based row index within the tile, \(0 \le i < M\)
\(j\) – zero-based column index within the tile, \(0 \le j < N\)
\(b\) – block index, \(0 \le b < \text{blocks}\)
lane – wavefront lane that holds the element, \(0 \le \text{lane} < 64\)
accVGPR – zero-based index into that lane’s private accumulator register file; the same index in two different lanes refers to two distinct physical registers
\(32 \times 32\) layout#
The \(32 \times 32\) tile shape uses two blocks. All 32 accVGPRs per lane are active: accVGPRs 0–15 belong to block 0, accVGPRs 16–31 to block 1.
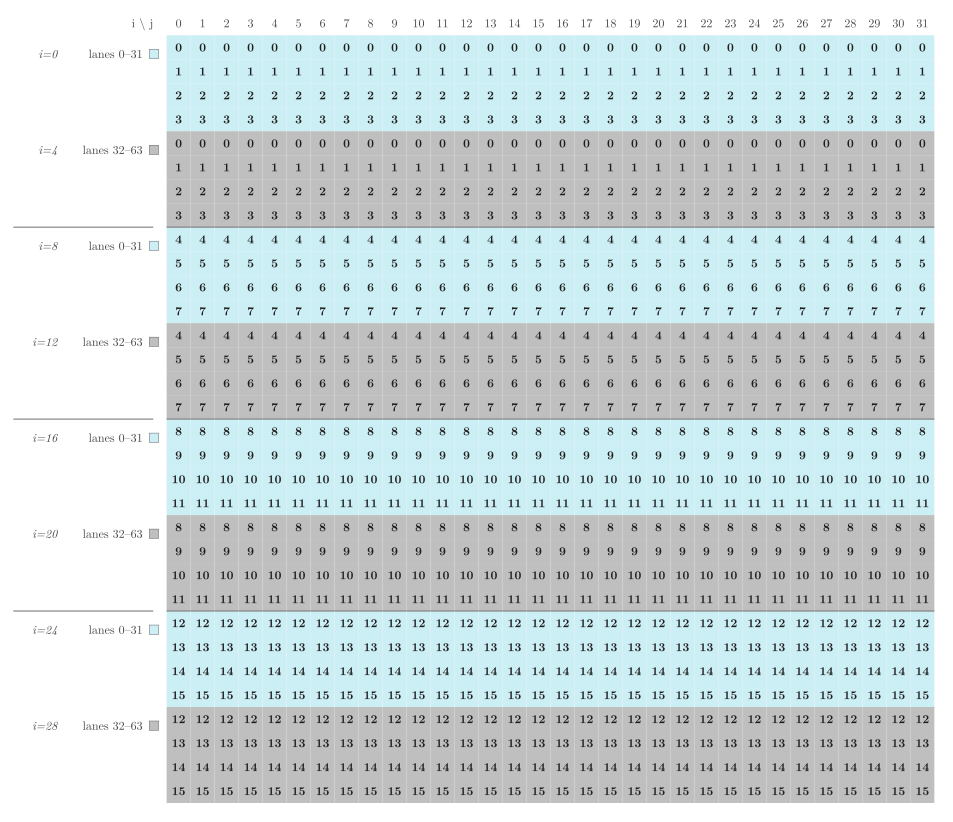
\(32 \times 32\) accumulator layout – 2 blocks. Each cell shows the accVGPR index that holds output element \((i, j)\) of block 0; block 1 adds 16. Teal cells (rows where \(\lfloor i/4 \rfloor\) is even) belong to lanes 0–31; grey cells to lanes 32–63. Column \(j\) gives the lane offset within the group.#
Given output element \((i, j)\) in block \(b\):
Conversely, given a lane \(L\) and accVGPR index \(G\):
The row-to-lane mapping groups rows in bands of four. Within block 0:
Rows |
Lanes |
accVGPRs |
|---|---|---|
0—3 |
0—31 |
0—3 |
4—7 |
32—63 |
0—3 |
8—11 |
0—31 |
4—7 |
12—15 |
32—63 |
4—7 |
16—19 |
0—31 |
8—11 |
20—23 |
32—63 |
8—11 |
24—27 |
0—31 |
12—15 |
28—31 |
32—63 |
12—15 |
Block 1 uses the same lane pattern with accVGPRs 16–31.
Builtins with a 1-block \(32 \times 32\) result (v16float /
v16int, 16 accVGPRs per lane) use only block 0 of the layout above.
These variants do not support the cbsz and abid modifiers.
\(16 \times 16\) layout#
The \(16 \times 16\) tile shape uses four blocks. The 16 accVGPRs per lane are partitioned by block: accVGPRs 0—3 for block 0, 4—7 for block 1, 8—11 for block 2, and 12—15 for block 3.
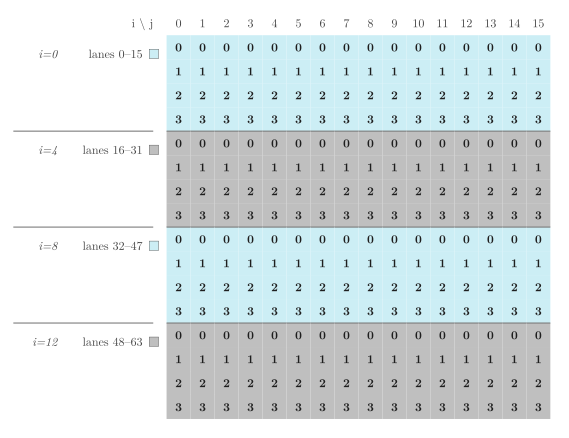
\(16 \times 16\) accumulator layout – 4 blocks. Each cell shows the accVGPR index for block 0; block \(k\) adds \(4k\). Rows 0—3 (teal, lanes 0—15), rows 4—7 (grey, lanes 16—31), rows 8—11 (teal, lanes 32—47), rows 12—15 (grey, lanes 48—63). Column \(j\) gives the lane offset within the group.#
Given output element \((i, j)\) in block \(b\):
Conversely, given lane \(L\) and accVGPR index \(G\):
The row-to-lane mapping (identical for every block):
Rows |
Lanes |
|---|---|
0—3 |
0—15 |
4—7 |
16—31 |
8—11 |
32—47 |
12—15 |
48—63 |
Builtins with a 1-block \(16 \times 16\) result (v4float /
v4int, 4 accVGPRs per lane) use only block 0 of the layout above.
These variants do not support the cbsz and abid modifiers.
\(4 \times 4\) layout#
The \(4 \times 4\) tile shape uses 16 blocks. A single wavefront simultaneously computes 16 independent \(4 \times 4\) outer products. Each group of 4 consecutive lanes (lanes \(4b\) through \(4b + 3\)) holds all 16 output elements of block \(b\) across 4 accVGPRs.

\(4 \times 4\) accumulator layout – 16 blocks. Columns are lanes 0–63; each group of 4 consecutive lanes holds one complete \(4 \times 4\) output tile in accVGPRs 0–3 (rows). Teal groups are even-numbered blocks, grey groups odd-numbered blocks.#
Given output element \((i, j)\) in block \(b\):
Conversely, given lane \(L\) and accVGPR index \(G\):
\(16 \times 16\) FP64 layout#
The \(16 \times 16\) FP64 tile shape uses one block. Each lane holds four FP64 output elements across 4 accVGPR pairs (8 physical accVGPRs, since each FP64 value occupies two 32-bit registers).
Note
FP64 accVGPR indices count pairs of physical registers. accVGPR pair
\(k\) corresponds to physical registers v[2k+1:2k].
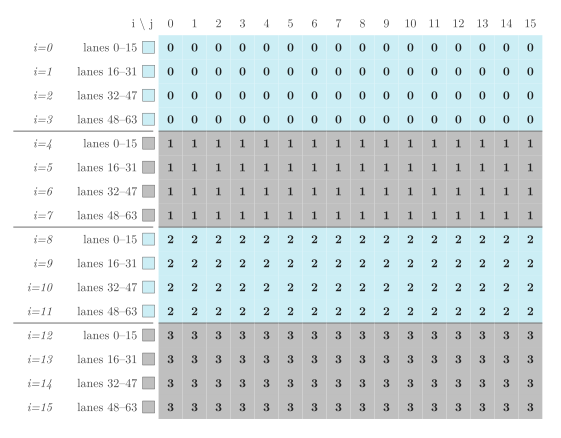
\(16 \times 16\) FP64 accumulator layout – 1 block. Each cell shows
the accVGPR pair index \(k\) that holds output element \((i, j)\);
physical registers are v[2k+1:2k]. Each group of 16 consecutive lanes
(column offset \(j\)) covers all four rows within one row-modulo-4 band.#
Given output element \((i, j)\):
Conversely, given lane \(L\) and accVGPR pair index \(k\):
The row-to-lane mapping. Each group of 16 consecutive lanes covers one row modulo 4; the accVGPR pair selects the row group:
Rows |
Lanes |
accVGPR pair (physical regs) |
|---|---|---|
0, 4, 8, 12 |
0—15 |
0, 1, 2, 3 ( |
1, 5, 9, 13 |
16—31 |
0, 1, 2, 3 |
2, 6, 10, 14 |
32—47 |
0, 1, 2, 3 |
3, 7, 11, 15 |
48—63 |
0, 1, 2, 3 |
\(4 \times 4\) FP64 layout#
The \(4 \times 4\) FP64 tile shape uses four blocks. Each lane holds one
FP64 output element in a single accVGPR pair (2 physical accVGPRs, v[1:0]).
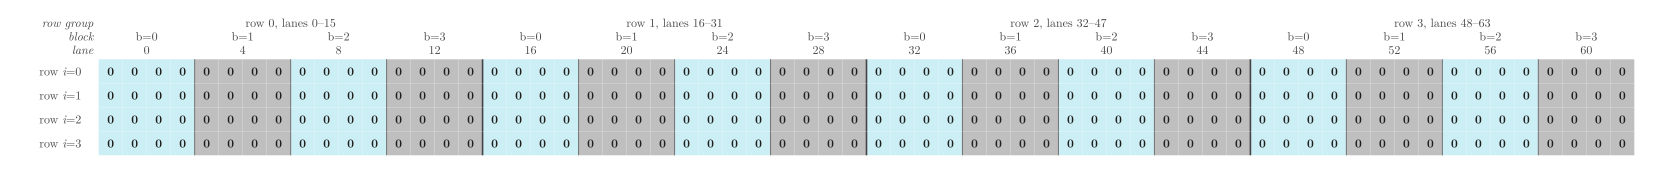
\(4 \times 4\) FP64 accumulator layout – 4 blocks. Columns are lanes
0–63; rows are matrix rows 0–3. Within each 16-lane row group, four
sub-groups of 4 lanes hold blocks 0–3. Every cell holds one FP64 value in
accVGPR pair 0 (v[1:0]). Teal sub-groups are even-numbered blocks, grey
sub-groups are odd-numbered blocks.#
Given output element \((i, j)\) in block \(b\):
Conversely, given lane \(L\):
The row-to-lane mapping. Lanes 0—15 hold all four blocks of row 0; the pattern repeats for rows 1—3 at lane offsets of 16, 32, and 48:
Row |
Block |
Lanes |
accVGPR pair |
|---|---|---|---|
0 |
0 |
0—3 |
0 ( |
0 |
1 |
4—7 |
0 ( |
0 |
2 |
8—11 |
0 ( |
0 |
3 |
12—15 |
0 ( |
1 |
0—3 |
16—31 |
0 ( |
2 |
0—3 |
32—47 |
0 ( |
3 |
0—3 |
48—63 |
0 ( |
Register types used in this reference#
The signatures below use the following type aliases, which you can declare with C++ attributes in any HIP translation unit:
using v4float   = float [[clang::ext_vector_type(4)]];
using v16float  = float [[clang::ext_vector_type(16)]];
using v32float  = float [[clang::ext_vector_type(32)]];
using v4half    = _Float16 [[clang::ext_vector_type(4)]];
using v8half    = _Float16 [[clang::ext_vector_type(8)]];
using v4int     = int [[clang::ext_vector_type(4)]];
using v6int     = int [[clang::ext_vector_type(6)]];        // FP6 scale inputs
using v8int     = int [[clang::ext_vector_type(8)]];        // FP8/BF8 scale inputs
using v16int    = int [[clang::ext_vector_type(16)]];
using v32int    = int [[clang::ext_vector_type(32)]];
using v2bfloat  = short [[clang::ext_vector_type(2)]];      // bf16 storage
using v4bfloat  = short [[clang::ext_vector_type(4)]];      // bf16 storage
using v8bfloat  = short [[clang::ext_vector_type(8)]];      // wider-K BF16
using v4double  = double [[clang::ext_vector_type(4)]];
FP8 and BF8 operands passed to the standard (non-scale) MFMA builtins use a
64-bit integer (long long) that packs eight 8-bit values per lane. The
scaled sub-byte builtins (mfma_scale_*) use v4int, v6int, or
v8int depending on the selected format; see the per-builtin reference for
details.
Each type alias maps one-to-one to the corresponding LLVM vector type used in the builtin definition. The number in the name is the element count per lane; the total VGPR count equals the element count multiplied by the element size in 32-bit words.
Common parameters#
See Common MFMA parameters for a complete description of the cbsz,
abid, and blgp modifiers shared by all MFMA builtins.
Using MFMA builtins as a compute policy#
The matrix multiplication tutorial in
Optimizing GEMM in HIP uses a ComputePolicy type
parameter to separate the multiply-accumulate logic from the rest of the
kernel. You can drop an MFMA-based policy into that framework without
changing the outer kernel.
The example below implements MfmaCdna4F16Policy using
v_mfma_f32_16x16x32_f16 – a \(16 \times 16\) FP16 builtin
available on CDNA4 (gfx950, MI350 series). Each wavefront computes
a single \(16 \times 16\) output tile; one block is active, giving 4
FP32 accVGPRs per lane.
The complete source file is available for download:
Policy constants
v_mfma_f32_16x16x32_f16 consumes 32 K-positions per call (K=32), so
k_step = 32. Each lane provides eight FP16 values (v8half) for
\(\pmb{A}\) and eight for \(\pmb{B}\); the 64 lanes partition
into four groups of 16, each group covering eight K-positions. The
entire \(16 \times 16\) tile belongs to one wavefront, so
thread_tile_m = thread_tile_n = 16 and effective_lanes = 64.
Accumulator layout
The builtin returns a v4float holding 4 FP32 values – one for each
accVGPR. The Accumulator struct wraps this directly. The layout
formulas from the Accumulator layout section
translate (lane, accVGPR) back to \((i, j)\) coordinates during
the store_c() pass.
Fragment loading
Because each lane provides eight FP16 values for K=32, each load_a
call reads eight consecutive scalars. Lane group \(g = \lfloor
\text{lane\_id} / 16 \rfloor\) covers K-positions ki + 8g through
ki + 8g + 7; within the group, lane offset lane_id mod 16 selects
one of the 16 \(\pmb{A}\)-rows (or \(\pmb{B}\)-columns). The
mma() method packs the eight values into a v8half before issuing
the instruction.
Note
The all-modifier-zero constraint means cbsz, abid, and blgp
must all be passed as 0. v_mfma_f32_16x16x32_f16 is
single-block only and does not support the cbsz/abid broadcast
mechanism or the blgp lane-group pattern modifier.
struct MfmaCdna4F16Policy
{
    // -- ComputePolicy constants ----------------------------------------------
    // One wavefront owns a 16×16 output tile.
    // All 64 lanes hold unique output elements (4 elements per lane).
    static constexpr int thread_tile_m   = 16;
    static constexpr int thread_tile_n   = 16;
    static constexpr int frag_size_m     = 8;
    static constexpr int frag_size_n     = 8;
    static constexpr int effective_lanes = 64;
    // v_mfma_f32_16x16x32_f16 consumes 32 K-positions per call (k_step=32).
    // Each lane provides eight FP16 values (v8half) for A and eight for B.
    // The 64 lanes split into 4 groups of 16; each group covers 8 K-positions.
    static constexpr int k_step          = 32;

    using elem_a = _Float16;
    using elem_b = _Float16;

    // -- Accumulator ----------------------------------------------------------
    // v4float holds 4 FP32 accVGPRs per lane (accVGPRs 0--3).
    using v4float = float [[clang::ext_vector_type(4)]];

    struct Accumulator
    {
        v4float regs;
    };

    __device__ static void zero(Accumulator& acc)
    {
        acc.regs = v4float{};
    }

    // -- thread_tile_offset ---------------------------------------------------
    // The entire 16×16 tile belongs to one wavefront.  Multiple wavefronts
    // in a block cover different 16×16 sub-tiles.
    //
    //   wavefront id within block: wid = tid / 64
    //   waves_n = block_tile_n / thread_tile_n = 32 / 16 = 2
    //   wid_x = wid % waves_n
    //   wid_y = wid / waves_n
    //   *thread_row = wid_y * 16
    //   *thread_col = wid_x * 16
    __device__ static void thread_tile_offset(int  tid,
                                              int  /*lane_id*/,
                                              int* thread_row,
                                              int* thread_col)
    {
        constexpr int waves_n = 2; // block_tile_n / thread_tile_n = 32 / 16
        const int wid   = tid / 64;
        const int wid_x = wid % waves_n;
        const int wid_y = wid / waves_n;
        *thread_row = wid_y * 16;
        *thread_col = wid_x * 16;
    }

    // -- Fragment loads --------------------------------------------------------
    // load_a: each lane reads eight FP16 values from LDS into a v8half.
    //
    // v_mfma_f32_16x16x32_f16 (1-block) interprets the 64 lanes as 4 groups
    // of 16 (indexed by g = lane_id / 16).  Each group covers 8 consecutive
    // K-positions: group g provides data for ki + 8*g through ki + 8*g + 7.
    // Within group g, lane offset (lane_id mod 16) selects one of the 16
    // A-rows.
    //
    //   A-row index : tile_a_row + (lane_id mod 16)
    //   K-position e: ki + 8*(lane_id / 16) + e   (e = 0..7)
    __device__ static void load_a(const _Float16* tile_a_ptr,
                                  int             tile_a_row,
                                  int             ki,
                                  int             k_tile_size,
                                  int             lane_id,
                                  elem_a        (&frag)[8])
    {
        const int row   = tile_a_row + (lane_id % 16);
        const int k_off = ki + 8 * (lane_id / 16);
        #pragma unroll
        for(int e = 0; e < 8; ++e)
            frag[e] = tile_a_ptr[row * k_tile_size + k_off + e];
    }

    // load_b: each lane reads eight FP16 values from LDS (symmetric to load_a).
    //
    // tile_b_T is stored transposed: tile_b_T[(tile_b_col + col)][k_off].
    //   B-col index : tile_b_col + (lane_id mod 16)
    //   K-position e: ki + 8*(lane_id / 16) + e   (e = 0..7)
    __device__ static void load_b(const _Float16* tile_b_T_ptr,
                                  int             tile_b_col,
                                  int             ki,
                                  int             k_tile_size,
                                  int             lane_id,
                                  elem_b        (&frag)[8])
    {
        const int col   = tile_b_col + (lane_id % 16);
        const int k_off = ki + 8 * (lane_id / 16);
        #pragma unroll
        for(int e = 0; e < 8; ++e)
            frag[e] = tile_b_T_ptr[col * k_tile_size + k_off + e];
    }

    // -- mma -------------------------------------------------------------------
    // Issue one v_mfma_f32_16x16x32_f16 instruction.
    // This intrinsic is single-block only; all modifier parameters must be 0.
    // cbsz=0, abid=0: single-block A-operand, no broadcast.
    // blgp=0: not supported; must be 0.
    __device__ static void mma(Accumulator&       acc,
                               const elem_a     (&a_frag)[8],
                               const elem_b     (&b_frag)[8])
    {
#if defined(__gfx950__)
        using v8half = _Float16 [[clang::ext_vector_type(8)]];
        const v8half a_vec = {a_frag[0], a_frag[1], a_frag[2], a_frag[3],
                              a_frag[4], a_frag[5], a_frag[6], a_frag[7]};
        const v8half b_vec = {b_frag[0], b_frag[1], b_frag[2], b_frag[3],
                              b_frag[4], b_frag[5], b_frag[6], b_frag[7]};
        acc.regs = __builtin_amdgcn_mfma_f32_16x16x32_f16(
            a_vec, b_vec, acc.regs,
            /*cbsz=*/0, /*abid=*/0, /*blgp=*/0);
#endif
    }

    // -- store_c ---------------------------------------------------------------
    // Scatter the 4 accVGPR values to their global-memory positions.
    //
    // Inverse layout (lane L, accVGPR index G in [0,3]):
    //   i = 4 * floor(L / 16) + (G mod 4)
    //   j = L mod 16
    __device__ static void store_c(const Accumulator& acc,
                                   float*             C,
                                   int                out_row_base,
                                   int                out_col_base,
                                   int                m,
                                   int                n,
                                   int                lane_id)
    {
        const int L = lane_id;
        const int j = L % 16;

        #pragma unroll
        for(int G = 0; G < 4; ++G)
        {
            const int i = 4 * (L / 16) + (G % 4);
            const int r = out_row_base + i;
            const int c = out_col_base + j;
            if(r < m && c < n)
                C[r * n + c] = acc.regs[G];
        }
    }
};
Instantiating the kernel
With MfmaCdna4F16Policy in hand, plug it into the generic kernel
alongside a TilePolicy whose block_tile_m and block_tile_n
are multiples of 16 and whose k_tile_size is a multiple of
k_step = 32. The policy aliases and launch configuration from the
example file are:
// TilePolicy for the standard FP16 path (transposed B in LDS).
using MfmaTilePolicy    = SingleBufferTilePolicyF16<32, 32, 32>;
// TilePolicy for the ds_read_tr path (row-major B in LDS).
using MfmaTilePolicyTrB = SingleBufferTilePolicyF16RowB<32, 32, 32>;
// Launch parameters:
//
// CDNA4 (gfx950): 2×2 wavefronts of 64 lanes = 256 threads per block.
//   block_tile_m = 32, thread_tile_m = 16  → 2 wavefronts along M
//   block_tile_n = 32, thread_tile_n = 16  → 2 wavefronts along N
//
// Fallback (scalar): 8×8 thread tiles in a 32×32 block → 16 threads per
//   block, padded to one full wavefront of 64.
//
// The kernel to launch and its thread count are selected at runtime based
// on the device architecture string returned by hipGetDeviceProperties.
//
// Grid: one block per 32×32 output tile.
constexpr int BLOCK_TILE_M = 32;
constexpr int BLOCK_TILE_N = 32;
    // Grid: one block per 32×32 output tile.
    const dim3 grid((N + BLOCK_TILE_N - 1) / BLOCK_TILE_N,
                    (M + BLOCK_TILE_M - 1) / BLOCK_TILE_M);

    float       ms = 0.0f;
    const char* policy_label = nullptr;

    if(is_gfx950)
    {
        // Standard path: scalar B load from transposed LDS tile.
        auto launch = [&]()
        {
            matrix_multiply_generic<MfmaTilePolicy,
                                    MfmaCdna4F16Policy,
                                    _Float16>
                <<<grid, dim3(256)>>>(d_A, d_B, d_C, M, N, K);
            HIP_CHECK(hipGetLastError());
        };
        ms           = time_kernel_ms(launch, WARMUP_RUNS, TIMING_RUNS);
        policy_label = "GemmKernel<MfmaTilePolicy, MfmaCdna4F16Policy> [gfx950]";

        // ds_read_tr path: hardware-transposed B load from row-major LDS tile.
        // Re-use the same device buffers; d_B was already uploaded.
        HIP_CHECK(hipMemset(d_C, 0, sizeof(float) * M * N));
        auto launch_tr = [&]()
        {
            matrix_multiply_generic<MfmaTilePolicyTrB,
                                    MfmaCdna4F16TrPolicy,
                                    _Float16>
                <<<grid, dim3(256)>>>(d_A, d_B, d_C, M, N, K);
            HIP_CHECK(hipGetLastError());
        };
        const float ms_tr = time_kernel_ms(launch_tr, WARMUP_RUNS, TIMING_RUNS);
        HIP_CHECK(hipMemcpy(h_C.data(), d_C, sizeof(float) * M * N,
                            hipMemcpyDeviceToHost));
        const bool ok_tr = verify_result(h_C, h_A, M, N, K);
        print_metrics(
            "GemmKernel<MfmaTilePolicyTrB, MfmaCdna4F16TrPolicy> [gfx950]",
            ok_tr, ms_tr, sizeof(_Float16), M, N, K);
    }
    else
    {
        // Scalar FP32 fallback: upload B as FP32.
        std::vector<float> h_B_f32(K * N, 0.0f);
        for(int i = 0; i < std::min(K, N); ++i)
            h_B_f32[i * N + i] = 1.0f;
        float* d_B_f32;
        HIP_CHECK(hipMalloc(&d_B_f32, sizeof(float) * K * N));
        HIP_CHECK(hipMemcpy(d_B_f32, h_B_f32.data(), sizeof(float) * K * N,
                            hipMemcpyHostToDevice));
        float* d_A_f32;
        HIP_CHECK(hipMalloc(&d_A_f32, sizeof(float) * M * K));
        std::vector<float> h_A_f32(M * K);
        for(int i = 0; i < M * K; ++i)
            h_A_f32[i] = static_cast<float>(h_A[i]);
        HIP_CHECK(hipMemcpy(d_A_f32, h_A_f32.data(), sizeof(float) * M * K,
                            hipMemcpyHostToDevice));

        auto launch = [&]()
        {
            matrix_multiply_generic<SingleBufferTilePolicyF<32, 32, 8>,
                                    ScalarFMAPolicy<8, 8, 8>,
                                    float>
                <<<grid, dim3(64)>>>(d_A_f32, d_B_f32, d_C, M, N, K);
            HIP_CHECK(hipGetLastError());
        };
        ms           = time_kernel_ms(launch, WARMUP_RUNS, TIMING_RUNS);
        policy_label = "GemmKernel<SingleBufferTilePolicyF, ScalarFMAPolicy> [fallback]";
        HIP_CHECK(hipFree(d_A_f32));
        HIP_CHECK(hipFree(d_B_f32));
    }
Compile and run:
amdclang++ -O3 -std=c++17 --offload-arch=gfx950 \
    matrix_multiply_cdna4_mfma.hip -o mm_cdna4_mfma
./mm_cdna4_mfma
Note
MfmaCdna4F16Policy requires a CDNA4 GPU (gfx950).
Compile with --offload-arch=gfx950 to select the correct
architecture. On other targets the #if defined(__gfx950__) guard
selects ScalarFMAPolicy automatically, so the file compiles without
modification.
Instruction throughput#
The cycle count below is the value used to compute theoretical peak throughput: \(\text{peak throughput} = \frac{\text{ops per instruction}}{\text{cycle count}} \times \text{clock frequency}\).
Builtin |
Ops |
Cycle count |
|---|---|---|
|
4096 |
64 |
|
2048 |
32 |
|
512 |
8 |
|
4096 |
64 |
|
2048 |
32 |
|
16384 |
64 |
|
8192 |
32 |
|
2048 |
8 |
|
16384 |
32 |
|
8192 |
16 |
|
32768 |
32 |
|
16384 |
16 |
|
16384 |
64 |
|
8192 |
32 |
|
2048 |
8 |
|
16384 |
32 |
|
8192 |
16 |
|
32768 |
32 |
|
16384 |
16 |
|
32768 |
32 |
|
32768 |
32 |
|
32768 |
32 |
|
32768 |
32 |
|
16384 |
16 |
|
16384 |
16 |
|
16384 |
16 |
|
16384 |
16 |
|
131072 |
32 (FP4/FP6), 64 (FP8/BF8) |
|
65536 |
16 (FP4/FP6), 32 (FP8/BF8) |
|
2048 |
64 |
|
512 |
32 |
|
16384 |
64 |
|
8192 |
32 |
|
2048 |
8 |
|
32768 |
32 |
|
16384 |
16 |
|
65536 |
32 |
|
32768 |
16 |
See also
CDNA4 MFMA transpose load builtins – Transpose load builtins that load operands directly from LDS into the per-lane fragment layout expected by the builtins below, without a software shuffle step.
Builtin reference#
FP32-accumulate builtins#
These builtins accumulate into single-precision (FP32) output fragments. They differ in the data type of the \(\pmb{A}\) and \(\pmb{B}\) matrix inputs.
FP32 matrix inputs#
The following builtins accept one FP32 element per lane for both \(\pmb{A}\) and \(\pmb{B}\) inputs and accumulate into FP32 output fragments.
__builtin_amdgcn_mfma_f32_32x32x1f32#
Signature and parameters for this builtin.
v32float __builtin_amdgcn_mfma_f32_32x32x1f32(
    float    srcA,
    float    srcB,
    v32float srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(32 \times 32\) FP32 outer-product accumulation. Each instruction processes \(K=1\) FP32 column element of \(\pmb{A}\) and \(K=1\) FP32 row element of \(\pmb{B}\), accumulating into a \(32 \times 32\) FP32 tile held across 32 accVGPRs per lane. This builtin operates on two input blocks.
Parameter |
Type |
Description |
|---|---|---|
|
float |
One element of \(\pmb{A}\) per lane. |
|
float |
One element of \(\pmb{B}\) per lane. |
|
v32float |
Accumulator input: 32 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters. Legal range: 0..1 |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier, see Common MFMA parameters. Legal range: 0..1 |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v32float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_16x16x1f32#
Signature and parameters for this builtin.
v16float __builtin_amdgcn_mfma_f32_16x16x1f32(
    float    srcA,
    float    srcB,
    v16float srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(16 \times 16\) FP32 outer-product accumulation. Each instruction processes \(K=1\) FP32 column element of \(\pmb{A}\) and \(K=1\) FP32 row element of \(\pmb{B}\), accumulating into a \(16 \times 16\) FP32 tile held across 16 accVGPRs per lane. This builtin operates on four input blocks.
Parameter |
Type |
Description |
|---|---|---|
|
float |
One element of \(\pmb{A}\) per lane. |
|
float |
One element of \(\pmb{B}\) per lane. |
|
v16float |
Accumulator input: 16 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters. Legal range: 0..2 |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier, see Common MFMA parameters. Legal range: 0..3 |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v16float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_4x4x1f32#
Signature and parameters for this builtin.
v4float __builtin_amdgcn_mfma_f32_4x4x1f32(
    float   srcA,
    float   srcB,
    v4float srcC,
    int     cbsz,
    int     abid,
    int     blgp);
Computes one step of a \(4 \times 4\) FP32 outer-product accumulation. Each instruction processes \(K=1\) FP32 column element of \(\pmb{A}\) and \(K=1\) FP32 row element of \(\pmb{B}\), accumulating into a \(4 \times 4\) FP32 tile held across 4 accVGPRs per lane. This builtin operates on 16 input blocks.
Parameter |
Type |
Description |
|---|---|---|
|
float |
One element of \(\pmb{A}\) per lane. |
|
float |
One element of \(\pmb{B}\) per lane. |
|
v4float |
Accumulator input: 4 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters. Legal range: 0..4 |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier, see Common MFMA parameters. Legal range: 0..15 |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v4float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_32x32x2f32#
Signature and parameters for this builtin.
v16float __builtin_amdgcn_mfma_f32_32x32x2f32(
    float    srcA,
    float    srcB,
    v16float srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(32 \times 32\) FP32 outer-product accumulation. Each instruction processes \(K=2\) FP32 column elements of \(\pmb{A}\) and \(K=2\) FP32 row elements of \(\pmb{B}\), accumulating into a \(32 \times 32\) FP32 tile held across 16 accVGPRs per lane. This builtin operates on a single input block.
Parameter |
Type |
Description |
|---|---|---|
|
float |
One element of \(\pmb{A}\) per lane. |
|
float |
One element of \(\pmb{B}\) per lane. |
|
v16float |
Accumulator input: 16 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v16float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_16x16x4f32#
Signature and parameters for this builtin.
v4float __builtin_amdgcn_mfma_f32_16x16x4f32(
    float   srcA,
    float   srcB,
    v4float srcC,
    int     cbsz,
    int     abid,
    int     blgp);
Computes one step of a \(16 \times 16\) FP32 outer-product accumulation. Each instruction processes \(K=4\) FP32 column elements of \(\pmb{A}\) and \(K=4\) FP32 row elements of \(\pmb{B}\), accumulating into a \(16 \times 16\) FP32 tile held across 4 accVGPRs per lane. This builtin operates on a single input block.
Parameter |
Type |
Description |
|---|---|---|
|
float |
One element of \(\pmb{A}\) per lane. |
|
float |
One element of \(\pmb{B}\) per lane. |
|
v4float |
Accumulator input: 4 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v4float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
FP16 matrix inputs#
CDNA4 supports two FP16 builtin families that differ in K step and block count.
The narrow-K multi-block variants accept four FP16 elements per lane packed into
a v4half register:
__builtin_amdgcn_mfma_f32_32x32x4f16#
Signature and parameters for this builtin.
v32float __builtin_amdgcn_mfma_f32_32x32x4f16(
    v4half   srcA,
    v4half   srcB,
    v32float srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(32 \times 32\) FP32 outer-product accumulation. Each instruction processes \(K=4\) FP16 column elements of \(\pmb{A}\) and \(K=4\) FP16 row elements of \(\pmb{B}\), accumulating into a \(32 \times 32\) FP32 tile held across 32 accVGPRs per lane. This builtin operates on two input blocks.
Parameter |
Type |
Description |
|---|---|---|
|
v4half |
Four elements of \(\pmb{A}\) per lane. |
|
v4half |
Four elements of \(\pmb{B}\) per lane. |
|
v32float |
Accumulator input: 32 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters. Legal range: 0..1 |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier, see Common MFMA parameters. Legal range: 0..1 |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v32float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_16x16x4f16#
Signature and parameters for this builtin.
v16float __builtin_amdgcn_mfma_f32_16x16x4f16(
    v4half   srcA,
    v4half   srcB,
    v16float srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(16 \times 16\) FP32 outer-product accumulation. Each instruction processes \(K=4\) FP16 column elements of \(\pmb{A}\) and \(K=4\) FP16 row elements of \(\pmb{B}\), accumulating into a \(16 \times 16\) FP32 tile held across 16 accVGPRs per lane. This builtin operates on four input blocks.
Parameter |
Type |
Description |
|---|---|---|
|
v4half |
Four elements of \(\pmb{A}\) per lane. |
|
v4half |
Four elements of \(\pmb{B}\) per lane. |
|
v16float |
Accumulator input: 16 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters. Legal range: 0..2 |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier, see Common MFMA parameters. Legal range: 0..3 |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v16float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_4x4x4f16#
Signature and parameters for this builtin.
v4float __builtin_amdgcn_mfma_f32_4x4x4f16(
    v4half  srcA,
    v4half  srcB,
    v4float srcC,
    int     cbsz,
    int     abid,
    int     blgp);
Computes one step of a \(4 \times 4\) FP32 outer-product accumulation. Each instruction processes \(K=4\) FP16 column elements of \(\pmb{A}\) and \(K=4\) FP16 row elements of \(\pmb{B}\), accumulating into a \(4 \times 4\) FP32 tile held across four accVGPRs per lane. This builtin operates on 16 input blocks.
Parameter |
Type |
Description |
|---|---|---|
|
v4half |
Four elements of \(\pmb{A}\) per lane. |
|
v4half |
Four elements of \(\pmb{B}\) per lane. |
|
v4float |
Accumulator input: Four FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters. Legal range: 0..4 |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier, see Common MFMA parameters. Legal range: 0..15 |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v4float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_32x32x8f16#
Signature and parameters for this builtin.
v16float __builtin_amdgcn_mfma_f32_32x32x8f16(
    v4half   srcA,
    v4half   srcB,
    v16float srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(32 \times 32\) FP32 outer-product accumulation. Each instruction processes \(K=8\) FP16 column elements of \(\pmb{A}\) and \(K=8\) FP16 row elements of \(\pmb{B}\), accumulating into a \(32 \times 32\) FP32 tile held across 16 accVGPRs per lane. This builtin operates on a single input block.
Parameter |
Type |
Description |
|---|---|---|
|
v4half |
Four elements of \(\pmb{A}\) per lane. |
|
v4half |
Four elements of \(\pmb{B}\) per lane. |
|
v16float |
Accumulator input: 16 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v16float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_16x16x16f16#
Signature and parameters for this builtin.
v4float __builtin_amdgcn_mfma_f32_16x16x16f16(
    v4half  srcA,
    v4half  srcB,
    v4float srcC,
    int     cbsz,
    int     abid,
    int     blgp);
Computes one step of a \(16 \times 16\) FP32 outer-product accumulation. Each instruction processes \(K=16\) FP16 column elements of \(\pmb{A}\) and \(K=16\) FP16 row elements of \(\pmb{B}\), accumulating into a \(16 \times 16\) FP32 tile held across four accVGPRs per lane. This builtin operates on a single input block.
Parameter |
Type |
Description |
|---|---|---|
|
v4half |
Four elements of \(\pmb{A}\) per lane. |
|
v4half |
Four elements of \(\pmb{B}\) per lane. |
|
v4float |
Accumulator input: Four FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v4float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
The wider-K single-block variants accept eight FP16 elements per lane packed
into a v8half register:
__builtin_amdgcn_mfma_f32_32x32x16_f16#
Signature and parameters for this builtin.
v16float __builtin_amdgcn_mfma_f32_32x32x16_f16(
    v8half   srcA,
    v8half   srcB,
    v16float srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(32 \times 32\) FP16→FP32 matrix
multiply-accumulate. Each instruction processes \(K=16\) FP16 column
elements of \(\pmb{A}\)
and \(K=16\) FP16 row elements of \(\pmb{B}\), accumulating into a
\(32 \times 32\) FP32 tile. Each lane holds eight FP16 values packed into
one v8half register for each of \(\pmb{A}\) and \(\pmb{B}\).
This is a single-block variant. The result is a v16float (16 FP32
elements per lane) using accVGPRs 0–15 in the \(32 \times 32\) layout.
Parameter |
Type |
Description |
|---|---|---|
|
v8half |
Eight FP16 elements of \(\pmb{A}\) per lane, packed into a 128-bit register. |
|
v8half |
Eight FP16 elements of \(\pmb{B}\) per lane, packed into a 128-bit register. |
|
v16float |
Accumulator input: 16 FP32 elements per lane. |
|
int |
Reserved. Must be |
|
int |
Reserved. Must be |
|
int |
Lane-group pattern modifier. See Common MFMA parameters. |
Returns v16float – updated accumulator.
Note
This single-block variant does not support the cbsz and abid
broadcast modifiers; both must be 0.
__builtin_amdgcn_mfma_f32_16x16x32_f16#
Signature and parameters for this builtin.
v4float __builtin_amdgcn_mfma_f32_16x16x32_f16(
    v8half  srcA,
    v8half  srcB,
    v4float srcC,
    int     cbsz,
    int     abid,
    int     blgp);
Computes one step of a \(16 \times 16\) FP16→FP32 matrix
multiply-accumulate. Each instruction processes \(K=32\) FP16 column
elements of \(\pmb{A}\)
and \(K=32\) FP16 row elements of \(\pmb{B}\), accumulating into a
\(16 \times 16\) FP32 tile. Each lane holds eight FP16 values packed into
one v8half register for each of \(\pmb{A}\) and \(\pmb{B}\).
This is a single-block variant. The result is a v4float (4 FP32 elements
per lane) using accVGPRs 0–3 in the \(16 \times 16\) layout.
Parameter |
Type |
Description |
|---|---|---|
|
v8half |
Eight FP16 elements of \(\pmb{A}\) per lane, packed into a 128-bit register. |
|
v8half |
Eight FP16 elements of \(\pmb{B}\) per lane, packed into a 128-bit register. |
|
v4float |
Accumulator input: 4 FP32 elements per lane. |
|
int |
Reserved. Must be |
|
int |
Reserved. Must be |
|
int |
Lane-group pattern modifier. See Common MFMA parameters. |
Returns v4float – updated accumulator.
Note
This single-block variant does not support the cbsz and abid
broadcast modifiers; both must be 0.
BF16 matrix inputs#
CDNA4 supports two BF16 builtin families that differ in K step and block count.
The narrow-K _1k multi-block variants, inherited from CDNA3, accept four
BF16 elements per lane packed into a v4bfloat register:
__builtin_amdgcn_mfma_f32_32x32x4bf16_1k#
Signature and parameters for this builtin.
v32float __builtin_amdgcn_mfma_f32_32x32x4bf16_1k(
    v4bfloat srcA,
    v4bfloat srcB,
    v32float srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(32 \times 32\) FP32 outer-product accumulation. Each instruction processes \(K=4\) BF16 column elements of \(\pmb{A}\) and \(K=4\) BF16 row elements of \(\pmb{B}\), accumulating into a \(32 \times 32\) FP32 tile held across 32 accVGPRs per lane. This builtin operates on two input blocks.
Parameter |
Type |
Description |
|---|---|---|
|
v4bfloat |
Four BF16 elements of \(\pmb{A}\) per lane. |
|
v4bfloat |
Four BF16 elements of \(\pmb{B}\) per lane. |
|
v32float |
Accumulator input: 32 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters. Legal range: 0..1 |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier, see Common MFMA parameters. Legal range: 0..1 |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v32float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_16x16x4bf16_1k#
Signature and parameters for this builtin.
v16float __builtin_amdgcn_mfma_f32_16x16x4bf16_1k(
    v4bfloat srcA,
    v4bfloat srcB,
    v16float srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(16 \times 16\) FP32 outer-product accumulation. Each instruction processes \(K=4\) BF16 column elements of \(\pmb{A}\) and \(K=4\) BF16 row elements of \(\pmb{B}\), accumulating into a \(16 \times 16\) FP32 tile held across 16 accVGPRs per lane. This builtin operates on four input blocks.
Parameter |
Type |
Description |
|---|---|---|
|
v4bfloat |
Four BF16 elements of \(\pmb{A}\) per lane. |
|
v4bfloat |
Four BF16 elements of \(\pmb{B}\) per lane. |
|
v16float |
Accumulator input: 16 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters. Legal range: 0..2 |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier, see Common MFMA parameters. Legal range: 0..3 |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v16float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_4x4x4bf16_1k#
Signature and parameters for this builtin.
v4float __builtin_amdgcn_mfma_f32_4x4x4bf16_1k(
    v4bfloat srcA,
    v4bfloat srcB,
    v4float  srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(4 \times 4\) FP32 outer-product accumulation. Each instruction processes \(K=4\) BF16 column elements of \(\pmb{A}\) and \(K=4\) BF16 row elements of \(\pmb{B}\), accumulating into a \(4 \times 4\) FP32 tile held across 4 accVGPRs per lane. This builtin operates on 16 input blocks.
Parameter |
Type |
Description |
|---|---|---|
|
v4bfloat |
Four BF16 elements of \(\pmb{A}\) per lane. |
|
v4bfloat |
Four BF16 elements of \(\pmb{B}\) per lane. |
|
v4float |
Accumulator input: 4 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters. Legal range: 0..4 |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier, see Common MFMA parameters. Legal range: 0..15 |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v4float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_32x32x8bf16_1k#
Signature and parameters for this builtin.
v16float __builtin_amdgcn_mfma_f32_32x32x8bf16_1k(
    v4bfloat srcA,
    v4bfloat srcB,
    v16float srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(32 \times 32\) FP32 outer-product accumulation. Each instruction processes \(K=8\) BF16 column elements of \(\pmb{A}\) and \(K=8\) BF16 row elements of \(\pmb{B}\), accumulating into a \(32 \times 32\) FP32 tile held across 16 accVGPRs per lane. This builtin operates on a single input block.
Parameter |
Type |
Description |
|---|---|---|
|
v4bfloat |
Four BF16 elements of \(\pmb{A}\) per lane. |
|
v4bfloat |
Four BF16 elements of \(\pmb{B}\) per lane. |
|
v16float |
Accumulator input: 16 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v16float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_16x16x16bf16_1k#
Signature and parameters for this builtin.
v4float __builtin_amdgcn_mfma_f32_16x16x16bf16_1k(
    v4bfloat srcA,
    v4bfloat srcB,
    v4float  srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(16 \times 16\) FP32 outer-product accumulation. Each instruction processes \(K=16\) BF16 column elements of \(\pmb{A}\) and \(K=16\) BF16 row elements of \(\pmb{B}\), accumulating into a \(16 \times 16\) FP32 tile held across 4 accVGPRs per lane. This builtin operates on a single input block.
Parameter |
Type |
Description |
|---|---|---|
|
v4bfloat |
Four BF16 elements of \(\pmb{A}\) per lane. |
|
v4bfloat |
Four BF16 elements of \(\pmb{B}\) per lane. |
|
v4float |
Accumulator input: 4 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v4float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
The wider-K single-block variants accept eight BF16 elements per lane packed
into a v8bfloat register:
__builtin_amdgcn_mfma_f32_32x32x16_bf16#
Signature and parameters for this builtin.
v16float __builtin_amdgcn_mfma_f32_32x32x16_bf16(
    v8bfloat srcA,
    v8bfloat srcB,
    v16float srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(32 \times 32\) BF16→FP32 matrix
multiply-accumulate. Each instruction processes \(K=16\) BF16 column
elements of \(\pmb{A}\)
and \(K=16\) BF16 row elements of \(\pmb{B}\), accumulating into a
\(32 \times 32\) FP32 tile. Each lane holds eight BF16 values packed into
one v8bfloat register (stored as short) for each of \(\pmb{A}\) and
\(\pmb{B}\).
This is a single-block variant. The result is a v16float (16 FP32
elements per lane) using accVGPRs 0–15 in the \(32 \times 32\) layout.
Parameter |
Type |
Description |
|---|---|---|
|
v8bfloat |
Eight BF16 elements of \(\pmb{A}\) per lane, stored as
|
|
v8bfloat |
Eight BF16 elements of \(\pmb{B}\) per lane, stored as
|
|
v16float |
Accumulator input: 16 FP32 elements per lane. |
|
int |
Reserved. Must be |
|
int |
Reserved. Must be |
|
int |
Lane-group pattern modifier. See Common MFMA parameters. |
Returns v16float – updated accumulator.
Note
This single-block variant does not support the cbsz and abid
broadcast modifiers; both must be 0.
__builtin_amdgcn_mfma_f32_16x16x32_bf16#
Signature and parameters for this builtin.
v4float __builtin_amdgcn_mfma_f32_16x16x32_bf16(
    v8bfloat srcA,
    v8bfloat srcB,
    v4float  srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(16 \times 16\) BF16→FP32 matrix
multiply-accumulate. Each instruction processes \(K=32\) BF16 column
elements of \(\pmb{A}\)
and \(K=32\) BF16 row elements of \(\pmb{B}\), accumulating into a
\(16 \times 16\) FP32 tile. Each lane holds eight BF16 values packed into
one v8bfloat register (stored as short) for each of \(\pmb{A}\) and
\(\pmb{B}\).
This is a single-block variant. The result is a v4float (4 FP32 elements
per lane) using accVGPRs 0–3 in the \(16 \times 16\) layout.
Parameter |
Type |
Description |
|---|---|---|
|
v8bfloat |
Eight BF16 elements of \(\pmb{A}\) per lane, stored as
|
|
v8bfloat |
Eight BF16 elements of \(\pmb{B}\) per lane, stored as
|
|
v4float |
Accumulator input: 4 FP32 elements per lane. |
|
int |
Reserved. Must be |
|
int |
Reserved. Must be |
|
int |
Lane-group pattern modifier. See Common MFMA parameters. |
Returns v4float – updated accumulator.
Note
This single-block variant does not support the cbsz and abid
broadcast modifiers; both must be 0.
FP8 and BF8 matrix inputs#
The following builtins accept eight 8-bit floating-point values per lane
packed into a long long register. Two 8-bit formats are supported:
FP8 (
fp8): E4M3 format (1 sign, 4 exponent, 3 mantissa bits).BF8 (
bf8): E5M2 format (1 sign, 5 exponent, 2 mantissa bits).
The \(\pmb{A}\) and \(\pmb{B}\) matrices can use different formats, giving four combinations per tile shape.
__builtin_amdgcn_mfma_f32_32x32x16_fp8_fp8#
Signature and parameters for this builtin.
v16float __builtin_amdgcn_mfma_f32_32x32x16_fp8_fp8(
    long long srcA,
    long long srcB,
    v16float  srcC,
    int       cbsz,
    int       abid,
    int       blgp);
Computes one step of a \(32 \times 32\) FP32 outer-product accumulation. Each instruction processes \(K=16\) FP8 column elements of \(\pmb{A}\) and \(K=16\) FP8 row elements of \(\pmb{B}\), accumulating into a \(32 \times 32\) FP32 tile held across 16 accVGPRs per lane. This builtin operates on a single input block.
Both \(\pmb{A}\) and \(\pmb{B}\) use the FP8 (E4M3) format: eight
8-bit values packed into a long long register per lane.
Parameter |
Type |
Description |
|---|---|---|
|
long long |
Eight FP8 (E4M3) elements of \(\pmb{A}\) per lane. |
|
long long |
Eight FP8 (E4M3) elements of \(\pmb{B}\) per lane. |
|
v16float |
Accumulator input: 16 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
Must be |
Returns v16float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_32x32x16_fp8_bf8#
Signature and parameters for this builtin.
v16float __builtin_amdgcn_mfma_f32_32x32x16_fp8_bf8(
    long long srcA,
    long long srcB,
    v16float  srcC,
    int       cbsz,
    int       abid,
    int       blgp);
Computes one step of a \(32 \times 32\) FP32 outer-product accumulation. Each instruction processes \(K=16\) FP8 column elements of \(\pmb{A}\) and \(K=16\) BF8 row elements of \(\pmb{B}\), accumulating into a \(32 \times 32\) FP32 tile held across 16 accVGPRs per lane. This builtin operates on a single input block.
\(\pmb{A}\) uses the FP8 (E4M3) format and \(\pmb{B}\) uses the BF8
(E5M2) format; eight 8-bit values are packed into a long long register per
lane for each operand.
Parameter |
Type |
Description |
|---|---|---|
|
long long |
Eight FP8 (E4M3) elements of \(\pmb{A}\) per lane. |
|
long long |
Eight BF8 (E5M2) elements of \(\pmb{B}\) per lane. |
|
v16float |
Accumulator input: 16 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
Must be |
Returns v16float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_32x32x16_bf8_fp8#
Signature and parameters for this builtin.
v16float __builtin_amdgcn_mfma_f32_32x32x16_bf8_fp8(
    long long srcA,
    long long srcB,
    v16float  srcC,
    int       cbsz,
    int       abid,
    int       blgp);
Computes one step of a \(32 \times 32\) FP32 outer-product accumulation. Each instruction processes \(K=16\) BF8 column elements of \(\pmb{A}\) and \(K=16\) FP8 row elements of \(\pmb{B}\), accumulating into a \(32 \times 32\) FP32 tile held across 16 accVGPRs per lane. This builtin operates on a single input block.
\(\pmb{A}\) uses the BF8 (E5M2) format and \(\pmb{B}\) uses the FP8
(E4M3) format; eight 8-bit values are packed into a long long register per
lane for each operand.
Parameter |
Type |
Description |
|---|---|---|
|
long long |
Eight BF8 (E5M2) elements of \(\pmb{A}\) per lane. |
|
long long |
Eight FP8 (E4M3) elements of \(\pmb{B}\) per lane. |
|
v16float |
Accumulator input: 16 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
Must be |
Returns v16float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_32x32x16_bf8_bf8#
Signature and parameters for this builtin.
v16float __builtin_amdgcn_mfma_f32_32x32x16_bf8_bf8(
    long long srcA,
    long long srcB,
    v16float  srcC,
    int       cbsz,
    int       abid,
    int       blgp);
Computes one step of a \(32 \times 32\) FP32 outer-product accumulation. Each instruction processes \(K=16\) BF8 column elements of \(\pmb{A}\) and \(K=16\) BF8 row elements of \(\pmb{B}\), accumulating into a \(32 \times 32\) FP32 tile held across 16 accVGPRs per lane. This builtin operates on a single input block.
Both \(\pmb{A}\) and \(\pmb{B}\) use the BF8 (E5M2) format: eight
8-bit values packed into a long long register per lane.
Parameter |
Type |
Description |
|---|---|---|
|
long long |
Eight BF8 (E5M2) elements of \(\pmb{A}\) per lane. |
|
long long |
Eight BF8 (E5M2) elements of \(\pmb{B}\) per lane. |
|
v16float |
Accumulator input: 16 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
Must be |
Returns v16float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_16x16x32_fp8_fp8#
Signature and parameters for this builtin.
v4float __builtin_amdgcn_mfma_f32_16x16x32_fp8_fp8(
    long long srcA,
    long long srcB,
    v4float   srcC,
    int       cbsz,
    int       abid,
    int       blgp);
Computes one step of a \(16 \times 16\) FP32 outer-product accumulation. Each instruction processes \(K=32\) FP8 column elements of \(\pmb{A}\) and \(K=32\) FP8 row elements of \(\pmb{B}\), accumulating into a \(16 \times 16\) FP32 tile held across 4 accVGPRs per lane. This builtin operates on a single input block.
Both \(\pmb{A}\) and \(\pmb{B}\) use the FP8 (E4M3) format: eight
8-bit values packed into a long long register per lane.
Parameter |
Type |
Description |
|---|---|---|
|
long long |
Eight FP8 (E4M3) elements of \(\pmb{A}\) per lane. |
|
long long |
Eight FP8 (E4M3) elements of \(\pmb{B}\) per lane. |
|
v4float |
Accumulator input: 4 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
Must be |
Returns v4float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_16x16x32_fp8_bf8#
Signature and parameters for this builtin.
v4float __builtin_amdgcn_mfma_f32_16x16x32_fp8_bf8(
    long long srcA,
    long long srcB,
    v4float   srcC,
    int       cbsz,
    int       abid,
    int       blgp);
Computes one step of a \(16 \times 16\) FP32 outer-product accumulation. Each instruction processes \(K=32\) FP8 column elements of \(\pmb{A}\) and \(K=32\) BF8 row elements of \(\pmb{B}\), accumulating into a \(16 \times 16\) FP32 tile held across 4 accVGPRs per lane. This builtin operates on a single input block.
\(\pmb{A}\) uses the FP8 (E4M3) format and \(\pmb{B}\) uses the BF8
(E5M2) format; eight 8-bit values are packed into a long long register per
lane for each operand.
Parameter |
Type |
Description |
|---|---|---|
|
long long |
Eight FP8 (E4M3) elements of \(\pmb{A}\) per lane. |
|
long long |
Eight BF8 (E5M2) elements of \(\pmb{B}\) per lane. |
|
v4float |
Accumulator input: 4 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
Must be |
Returns v4float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_16x16x32_bf8_fp8#
Signature and parameters for this builtin.
v4float __builtin_amdgcn_mfma_f32_16x16x32_bf8_fp8(
    long long srcA,
    long long srcB,
    v4float   srcC,
    int       cbsz,
    int       abid,
    int       blgp);
Computes one step of a \(16 \times 16\) FP32 outer-product accumulation. Each instruction processes \(K=32\) BF8 column elements of \(\pmb{A}\) and \(K=32\) FP8 row elements of \(\pmb{B}\), accumulating into a \(16 \times 16\) FP32 tile held across 4 accVGPRs per lane. This builtin operates on a single input block.
\(\pmb{A}\) uses the BF8 (E5M2) format and \(\pmb{B}\) uses the FP8
(E4M3) format; eight 8-bit values are packed into a long long register per
lane for each operand.
Parameter |
Type |
Description |
|---|---|---|
|
long long |
Eight BF8 (E5M2) elements of \(\pmb{A}\) per lane. |
|
long long |
Eight FP8 (E4M3) elements of \(\pmb{B}\) per lane. |
|
v4float |
Accumulator input: 4 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
Must be |
Returns v4float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_f32_16x16x32_bf8_bf8#
Signature and parameters for this builtin.
v4float __builtin_amdgcn_mfma_f32_16x16x32_bf8_bf8(
    long long srcA,
    long long srcB,
    v4float   srcC,
    int       cbsz,
    int       abid,
    int       blgp);
Computes one step of a \(16 \times 16\) FP32 outer-product accumulation. Each instruction processes \(K=32\) BF8 column elements of \(\pmb{A}\) and \(K=32\) BF8 row elements of \(\pmb{B}\), accumulating into a \(16 \times 16\) FP32 tile held across 4 accVGPRs per lane. This builtin operates on a single input block.
Both \(\pmb{A}\) and \(\pmb{B}\) use the BF8 (E5M2) format: eight
8-bit values packed into a long long register per lane.
Parameter |
Type |
Description |
|---|---|---|
|
long long |
Eight BF8 (E5M2) elements of \(\pmb{A}\) per lane. |
|
long long |
Eight BF8 (E5M2) elements of \(\pmb{B}\) per lane. |
|
v4float |
Accumulator input: 4 FP32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
Must be |
Returns v4float – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
FP64-accumulate builtins#
CDNA4 retains native double-precision (FP64) matrix accumulation from
CDNA3. These builtins accept one FP64 element per lane for both
\(\pmb{A}\) and \(\pmb{B}\) inputs and accumulate into FP64 output
fragments held in v4double registers.
Note
On CDNA4, the blgp parameter of FP64 builtins is repurposed as a
3-bit source negation modifier rather than a lane-group pattern selector.
See the Common parameters section for details.
FP64 matrix inputs#
The following builtins accept one FP64 element per lane for both \(\pmb{A}\) and \(\pmb{B}\) inputs and accumulate into FP64 output fragments.
__builtin_amdgcn_mfma_f64_16x16x4f64#
Signature and parameters for this builtin.
v4double __builtin_amdgcn_mfma_f64_16x16x4f64(
    double   srcA,
    double   srcB,
    v4double srcC,
    int      cbsz,
    int      abid,
    int      blgp);
Computes one step of a \(16 \times 16\) FP64 outer-product accumulation. Each instruction processes \(K=4\) FP64 column elements of \(\pmb{A}\) and \(K=4\) FP64 row elements of \(\pmb{B}\), accumulating into a \(16 \times 16\) FP64 tile held across 4 accVGPRs per lane (8 physical accVGPRs, since each FP64 value occupies two 32-bit registers). This builtin operates on a single input block.
Parameter |
Type |
Description |
|---|---|---|
|
double |
One FP64 element of \(\pmb{A}\) per lane. |
|
double |
One FP64 element of \(\pmb{B}\) per lane. |
|
v4double |
Accumulator input: 4 FP64 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, repurposed as a
negation modifier (3-bit field). Bit 0 negates |
Returns v4double – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
Note
Unlike most FP32, BF16, and INT8 MFMA instructions, FP64 MFMA instructions cannot co-execute with VALU instructions. To hide execution latency, schedule non-VALU instructions (loads, stores, or branches) around FP64 MFMA operations.
__builtin_amdgcn_mfma_f64_4x4x4f64#
Signature and parameters for this builtin.
double __builtin_amdgcn_mfma_f64_4x4x4f64(
    double srcA,
    double srcB,
    double srcC,
    int    cbsz,
    int    abid,
    int    blgp);
Computes one step of a \(4 \times 4\) FP64 outer-product accumulation. Each instruction processes \(K=4\) FP64 column elements of \(\pmb{A}\) and \(K=4\) FP64 row elements of \(\pmb{B}\), accumulating into a \(4 \times 4\) FP64 tile. Each lane holds one FP64 output element across four input blocks.
Parameter |
Type |
Description |
|---|---|---|
|
double |
One FP64 element of \(\pmb{A}\) per lane. |
|
double |
One FP64 element of \(\pmb{B}\) per lane. |
|
double |
Accumulator input: 1 FP64 element per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, repurposed as a
negation modifier (3-bit field). Bit 0 negates |
Returns double – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
Note
Unlike most FP32, BF16, and INT8 MFMA instructions, FP64 MFMA instructions cannot co-execute with VALU instructions. To hide execution latency, schedule non-VALU instructions (loads, stores, or branches) around FP64 MFMA operations.
INT32-accumulate builtins#
These builtins accumulate into signed 32-bit integer (INT32) output fragments.
INT8 matrix inputs#
The following builtins accept four signed 8-bit integer elements per lane
packed into a single int register for both \(\pmb{A}\) and
\(\pmb{B}\) inputs.
__builtin_amdgcn_mfma_i32_32x32x4i8#
Signature and parameters for this builtin.
v32int __builtin_amdgcn_mfma_i32_32x32x4i8(
    int    srcA,
    int    srcB,
    v32int srcC,
    int    cbsz,
    int    abid,
    int    blgp);
Computes one step of a \(32 \times 32\) INT32 outer-product accumulation. Each instruction processes \(K=4\) INT8 column elements of \(\pmb{A}\) and \(K=4\) INT8 row elements of \(\pmb{B}\), accumulating into a \(32 \times 32\) INT32 tile held across 32 accVGPRs per lane. This builtin operates on two input blocks.
Parameter |
Type |
Description |
|---|---|---|
|
int |
Four elements of \(\pmb{A}\) per lane. |
|
int |
Four elements of \(\pmb{B}\) per lane. |
|
v32int |
Accumulator input: 32 INT32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters. Legal range: 0..1 |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier, see Common MFMA parameters. Legal range: 0..1 |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v32int – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_i32_16x16x4i8#
Signature and parameters for this builtin.
v16int __builtin_amdgcn_mfma_i32_16x16x4i8(
    int    srcA,
    int    srcB,
    v16int srcC,
    int    cbsz,
    int    abid,
    int    blgp);
Computes one step of a \(16 \times 16\) INT32 outer-product accumulation. Each instruction processes \(K=4\) INT8 column elements of \(\pmb{A}\) and \(K=4\) INT8 row elements of \(\pmb{B}\), accumulating into a \(16 \times 16\) INT32 tile held across 16 accVGPRs per lane. This builtin operates on four input blocks.
Parameter |
Type |
Description |
|---|---|---|
|
int |
Four elements of \(\pmb{A}\) per lane. |
|
int |
Four elements of \(\pmb{B}\) per lane. |
|
v16int |
Accumulator input: 16 INT32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters. Legal range: 0..2 |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier, see Common MFMA parameters. Legal range: 0..3 |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v16int – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_i32_4x4x4i8#
Signature and parameters for this builtin.
v4int __builtin_amdgcn_mfma_i32_4x4x4i8(
    int   srcA,
    int   srcB,
    v4int srcC,
    int   cbsz,
    int   abid,
    int   blgp);
Computes one step of a \(4 \times 4\) INT32 outer-product accumulation. Each instruction processes \(K=4\) INT8 column elements of \(\pmb{A}\) and \(K=4\) INT8 row elements of \(\pmb{B}\), accumulating into a \(4 \times 4\) INT32 tile held across 4 accVGPRs per lane. This builtin operates on 16 input blocks.
Parameter |
Type |
Description |
|---|---|---|
|
int |
Four elements of \(\pmb{A}\) per lane. |
|
int |
Four elements of \(\pmb{B}\) per lane. |
|
v4int |
Accumulator input: 4 INT32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters. Legal range: 0..4 |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier, see Common MFMA parameters. Legal range: 0..15 |
|
int |
\(\pmb{B}\)-matrix Lane Group Pattern modifier, see Common MFMA parameters. |
Returns v4int – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
The following wider-K variants accept eight signed 8-bit integer elements
per lane packed into a long long register:
__builtin_amdgcn_mfma_i32_32x32x16_i8#
Signature and parameters for this builtin.
v16int __builtin_amdgcn_mfma_i32_32x32x16_i8(
    long long srcA,
    long long srcB,
    v16int    srcC,
    int       cbsz,
    int       abid,
    int       blgp);
Computes one step of a \(32 \times 32\) INT32 outer-product accumulation. Each instruction processes \(K=16\) INT8 column elements of \(\pmb{A}\) and \(K=16\) INT8 row elements of \(\pmb{B}\), accumulating into a \(32 \times 32\) INT32 tile held across 16 accVGPRs per lane. This builtin operates on a single input block.
Each lane provides eight signed 8-bit integer values packed into a long long
register for both \(\pmb{A}\) and \(\pmb{B}\).
Parameter |
Type |
Description |
|---|---|---|
|
long long |
Eight INT8 elements of \(\pmb{A}\) per lane. |
|
long long |
Eight INT8 elements of \(\pmb{B}\) per lane. |
|
v16int |
Accumulator input: 16 INT32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
Must be |
Returns v16int – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
__builtin_amdgcn_mfma_i32_16x16x32_i8#
Signature and parameters for this builtin.
v4int __builtin_amdgcn_mfma_i32_16x16x32_i8(
    long long srcA,
    long long srcB,
    v4int     srcC,
    int       cbsz,
    int       abid,
    int       blgp);
Computes one step of a \(16 \times 16\) INT32 outer-product accumulation. Each instruction processes \(K=32\) INT8 column elements of \(\pmb{A}\) and \(K=32\) INT8 row elements of \(\pmb{B}\), accumulating into a \(16 \times 16\) INT32 tile held across 4 accVGPRs per lane. This builtin operates on a single input block.
Each lane provides eight signed 8-bit integer values packed into a long long
register for both \(\pmb{A}\) and \(\pmb{B}\).
Parameter |
Type |
Description |
|---|---|---|
|
long long |
Eight INT8 elements of \(\pmb{A}\) per lane. |
|
long long |
Eight INT8 elements of \(\pmb{B}\) per lane. |
|
v4int |
Accumulator input: 4 INT32 elements per lane. |
|
int |
Control Broadcast Size modifier, see Common MFMA parameters.
Must be |
|
int |
\(\pmb{A}\)-matrix Broadcast Identifier,
see Common MFMA parameters.
Must be |
|
int |
Must be |
Returns v4int – updated accumulator
(\(\text{srcA} \times \text{srcB} + \text{srcC}\)).
The following CDNA4 wider-K single-block variants accept 16 signed 8-bit integer
elements per lane packed into a v4int (four 32-bit words) register:
__builtin_amdgcn_mfma_i32_32x32x32_i8#
Signature and parameters for this builtin.
v16int __builtin_amdgcn_mfma_i32_32x32x32_i8(
    v4int  srcA,
    v4int  srcB,
    v16int srcC,
    int    cbsz,
    int    abid,
    int    blgp);
Computes one step of a \(32 \times 32\) INT8→INT32 matrix
multiply-accumulate. Each instruction processes \(K=32\) INT8 column
elements of \(\pmb{A}\)
and \(K=32\) INT8 row elements of \(\pmb{B}\), accumulating into a
\(32 \times 32\) INT32 tile. Each lane holds 16 signed 8-bit integers packed
into a v4int (four 32-bit words) for each of \(\pmb{A}\) and
\(\pmb{B}\).
This is a single-block variant. The result is a v16int (16 INT32
elements per lane) using accVGPRs 0–15 in the \(32 \times 32\) layout.
Parameter |
Type |
Description |
|---|---|---|
|
v4int |
Sixteen INT8 elements of \(\pmb{A}\) per lane, packed as four 32-bit words. |
|
v4int |
Sixteen INT8 elements of \(\pmb{B}\) per lane, packed as four 32-bit words. |
|
v16int |
Accumulator input: 16 INT32 elements per lane. |
|
int |
Reserved. Must be |
|
int |
Reserved. Must be |
|
int |
Lane-group pattern modifier. See Common MFMA parameters. |
Returns v16int – updated accumulator.
Note
This single-block variant does not support the cbsz and abid
broadcast modifiers; both must be 0.
__builtin_amdgcn_mfma_i32_16x16x64_i8#
Signature and parameters for this builtin.
v4int __builtin_amdgcn_mfma_i32_16x16x64_i8(
    v4int srcA,
    v4int srcB,
    v4int srcC,
    int   cbsz,
    int   abid,
    int   blgp);
Computes one step of a \(16 \times 16\) INT8→INT32 matrix
multiply-accumulate. Each instruction processes \(K=64\) INT8 column
elements of \(\pmb{A}\)
and \(K=64\) INT8 row elements of \(\pmb{B}\), accumulating into a
\(16 \times 16\) INT32 tile. Each lane holds 16 signed 8-bit integers packed
into a v4int (four 32-bit words) for each of \(\pmb{A}\) and
\(\pmb{B}\).
This is a single-block variant. The result is a v4int (4 INT32 elements
per lane) using accVGPRs 0–3 in the \(16 \times 16\) layout.
Parameter |
Type |
Description |
|---|---|---|
|
v4int |
Sixteen INT8 elements of \(\pmb{A}\) per lane, packed as four 32-bit words. |
|
v4int |
Sixteen INT8 elements of \(\pmb{B}\) per lane, packed as four 32-bit words. |
|
v4int |
Accumulator input: 4 INT32 elements per lane. |
|
int |
Reserved. Must be |
|
int |
Reserved. Must be |
|
int |
Lane-group pattern modifier. See Common MFMA parameters. |
Returns v4int – updated accumulator.
Note
This single-block variant does not support the cbsz and abid
broadcast modifiers; both must be 0.
Mixed-precision with scaling#
CDNA4 introduces scaled sub-byte matrix builtins (mfma_scale_*) that
support FP8 (E4M3), BF8 (E5M2), FP6 (E2M3), FP6 (E3M2), and FP4 (E2M1)
input formats with per-block scaling. Unlike the standard MFMA builtins,
the cbsz and blgp parameters select the input format for
\(\pmb{A}\) and \(\pmb{B}\) respectively rather than acting as
broadcast or lane-group-pattern modifiers. The vector type of srcA and
srcB must match the selected format: v8int for 8-bit formats, v6int
for 6-bit formats, and v4int for 4-bit formats.
Each instruction also accepts a pair of per-block scale values loaded with
v_mfma_ld_scale_b32. The 2-bit op_sel_a and op_sel_b immediates
select which quarter of the scale register applies to each output block.
FP8, FP6, and FP4 matrix inputs#
The following builtins accept scaled sub-byte matrix inputs with per-block scaling.
__builtin_amdgcn_mfma_scale_f32_32x32x64_f8f6f4#
Signature and parameters for this builtin.
v16float __builtin_amdgcn_mfma_scale_f32_32x32x64_f8f6f4(
    <vector>  srcA,
    <vector>  srcB,
    v16float  srcC,
    int       cbsz,
    int       blgp,
    int       op_sel_a,
    int       scale_a,
    int       op_sel_b,
    int       scale_b);
Computes one step of a \(32 \times 32\) scaled sub-byte matrix
multiply-accumulate. Each instruction processes \(K=64\) elements drawn
from a sub-byte floating-point format and accumulates into a
\(32 \times 32\) FP32 tile. The \(\pmb{A}\) and \(\pmb{B}\)
input formats are selected independently at compile time by cbsz and
blgp, and each block of
output elements is scaled by a per-block scale factor loaded with
v_mfma_ld_scale_b32.
This is a single-block variant. The result is a v16float (16 FP32
elements per lane) using accVGPRs 0–15 in the \(32 \times 32\) layout.
The vector type of srcA and srcB depends on the format specified by
cbsz and blgp respectively:
Format code ( |
Format |
Vector type |
Bits per element |
|---|---|---|---|
|
FP8 (E4M3) |
|
8 |
|
BF8 (E5M2) |
|
8 |
|
FP6 (E2M3) |
|
6 |
|
FP6 (E3M2) |
|
6 |
|
FP4 (E2M1) |
|
4 |
The srcA vector type must be consistent with the format selected by
cbsz, and the srcB vector type must be consistent with the format
selected by blgp. Mixing a vector type with an incompatible format
code is undefined behavior.
Parameter |
Type |
Description |
|---|---|---|
|
|
\(\pmb{A}\) matrix fragment per lane; element type and packing
determined by |
|
|
\(\pmb{B}\) matrix fragment per lane; element type and packing
determined by |
|
v16float |
Accumulator input: 16 FP32 elements per lane. |
|
int (immediate) |
Format selector for \(\pmb{A}\). Must be a compile-time constant in the range 0–4. See the format table above. |
|
int (immediate) |
Format selector for \(\pmb{B}\). Must be a compile-time constant in the range 0–4. See the format table above. |
|
int (immediate) |
2-bit selector that picks which quarter of |
|
int |
Per-block scale register for \(\pmb{A}\). Applied to all \(\pmb{A}\) input values before accumulation. |
|
int (immediate) |
2-bit selector that picks which quarter of |
|
int |
Per-block scale register for \(\pmb{B}\). Applied to all \(\pmb{B}\) input values before accumulation. |
Returns v16float – updated accumulator.
Note
Unlike the standard cbsz and blgp modifiers described in
Common MFMA parameters, in this builtin cbsz and blgp
are format selectors, not broadcast and lane-group-pattern modifiers.
Note
This instruction uses round-toward-nearest-even semantics.
__builtin_amdgcn_mfma_scale_f32_16x16x128_f8f6f4#
Signature and parameters for this builtin.
v4float __builtin_amdgcn_mfma_scale_f32_16x16x128_f8f6f4(
    <vector>  srcA,
    <vector>  srcB,
    v4float   srcC,
    int       cbsz,
    int       blgp,
    int       op_sel_a,
    int       scale_a,
    int       op_sel_b,
    int       scale_b);
Computes one step of a \(16 \times 16\) scaled sub-byte matrix
multiply-accumulate. Each instruction processes \(K=128\) elements drawn
from a sub-byte floating-point format and accumulates into a
\(16 \times 16\) FP32 tile. The \(\pmb{A}\) and \(\pmb{B}\)
input formats are selected independently at compile time by cbsz and
blgp, and each block of
output elements is scaled by a per-block scale factor loaded with
v_mfma_ld_scale_b32.
This is a single-block variant. The result is a v4float (4 FP32 elements
per lane) using accVGPRs 0–3 in the \(16 \times 16\) layout.
The vector type of srcA and srcB depends on the format specified by
cbsz and blgp respectively:
Format code ( |
Format |
Vector type |
Bits per element |
|---|---|---|---|
|
FP8 (E4M3) |
|
8 |
|
BF8 (E5M2) |
|
8 |
|
FP6 (E2M3) |
|
6 |
|
FP6 (E3M2) |
|
6 |
|
FP4 (E2M1) |
|
4 |
The srcA vector type must be consistent with the format selected by
cbsz, and the srcB vector type must be consistent with the format
selected by blgp. Mixing a vector type with an incompatible format code
is undefined behavior.
Parameter |
Type |
Description |
|---|---|---|
|
|
\(\pmb{A}\) matrix fragment per lane; element type and packing
determined by |
|
|
\(\pmb{B}\) matrix fragment per lane; element type and packing
determined by |
|
v4float |
Accumulator input: 4 FP32 elements per lane. |
|
int (immediate) |
Format selector for \(\pmb{A}\). Must be a compile-time constant in the range 0–4. See the format table above. |
|
int (immediate) |
Format selector for \(\pmb{B}\). Must be a compile-time constant in the range 0–4. See the format table above. |
|
int (immediate) |
2-bit selector that picks which quarter of |
|
int |
Per-block scale register for \(\pmb{A}\), loaded with
|
|
int (immediate) |
2-bit selector that picks which quarter of |
|
int |
Per-block scale register for \(\pmb{B}\), loaded with
|
Returns v4float – updated accumulator.
Note
Unlike the standard cbsz and blgp modifiers described in
Common MFMA parameters, in this builtin cbsz and blgp
are format selectors, not broadcast and lane-group-pattern modifiers.
Note
This builtin uses round-toward-nearest-even semantics.